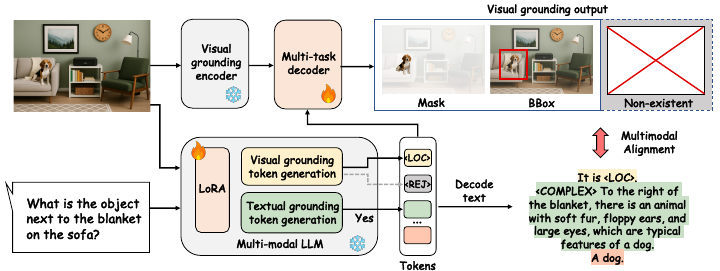
PostAlign: Multimodal Grounding as a Corrective Lens for MLLMs
Connects model answers to visual regions and textual rationales to improve fine-grained understanding.
Hi, I am Yixuan Wu (Chloe). I joined Alibaba DAMO Academy as a Researcher through the Alibaba Star Program, working on multimodal foundation models. I also hold a research position at Zhejiang University, working with Prof. Jian Wu.
I pursued my Ph.D. at Zhejiang University under the supervision of Prof. Jian Wu and work closely with Assistant Prof. Jintai Chen. During my Ph.D., I was a Visiting Scholar with the Torr Vision Group (TVG) at the University of Oxford, working with Prof. Philip Torr and Dr. Jindong Gu. I completed my undergraduate studies at Zhejiang University, during which I was a visiting student at Yale University.
My research interests include multimodal foundation models, fine-grained perception and reasoning, and medical AI. I welcome research collaborations with colleagues in academia and industry and am happy to connect for a ☕ coffee chat. If you are interested in an internship at Alibaba DAMO Academy or Zhejiang University's RealDoctor AI Research Center, please email me your CV.
A selection of papers, organized by research direction. For the complete and current list, visit Google Scholar.
Connects model answers to visual regions and textual rationales to improve fine-grained understanding.
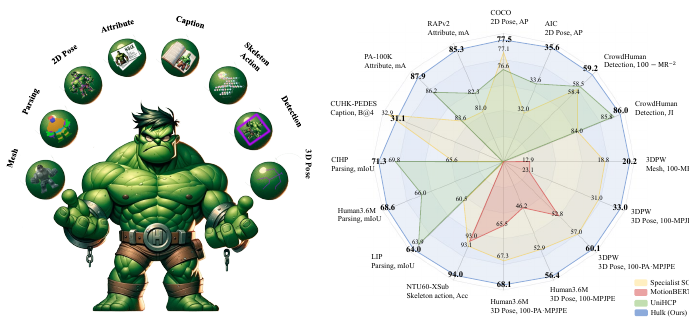
Unifies 2D, 3D, skeleton, and vision-language human-centric tasks without task-specific fine-tuning.
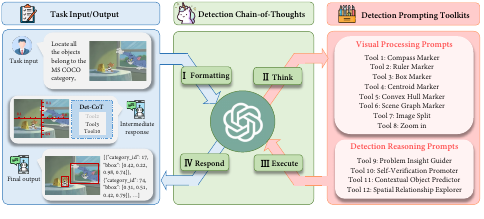
A prompting toolkit and detection reasoning chain for zero-shot object detection with MLLMs.
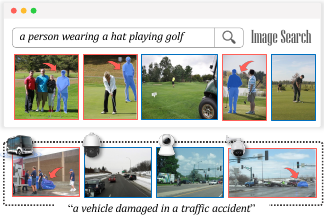
Extends referring expression segmentation from one image to image groups, including images where the target is absent.
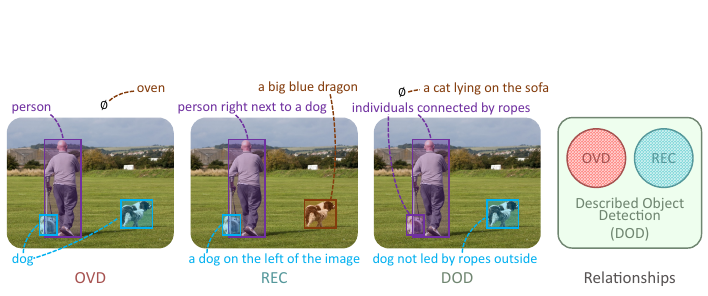
Introduces the D³ benchmark for detecting all objects specified by flexible language descriptions, including absent targets.
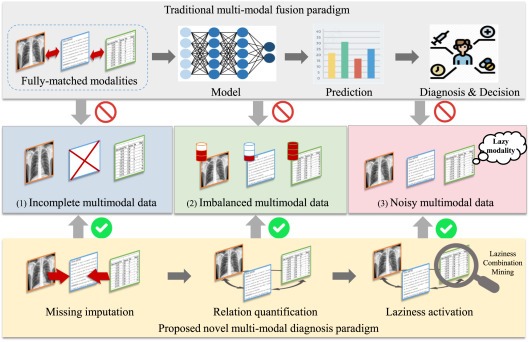
Addresses missing, imbalanced, and noisy modalities in medical prediction.
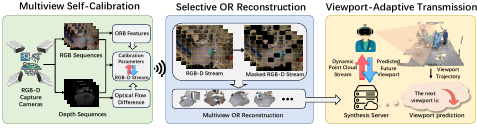
Reconstructs and streams operating-room scenes in real time to support remote surgical guidance.
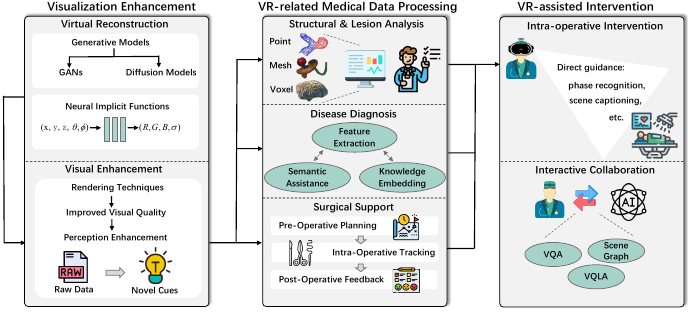
Surveys how AI-enhanced virtual reality supports medical visualization, data processing, and intervention.
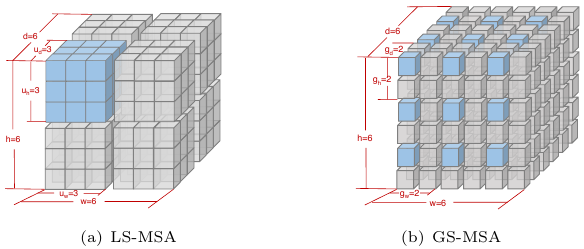
Combines local and dilated global attention in a U-shaped transformer for efficient 3D medical image segmentation.
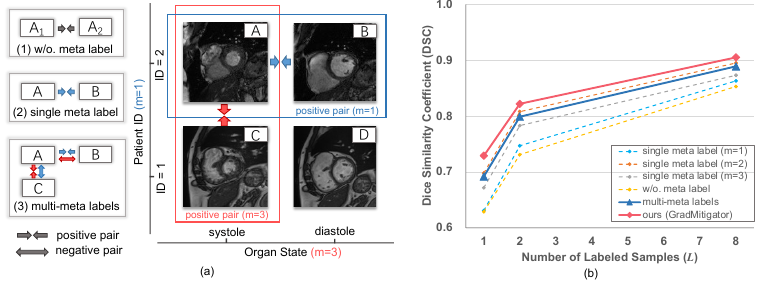
Uses gradient-guided contrastive learning to reconcile multiple meta labels and improve segmentation with limited annotations.
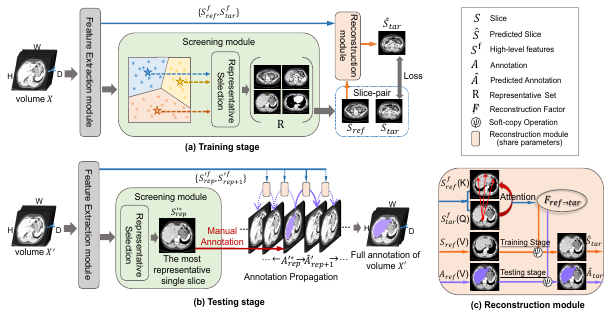
Propagates one annotated slice through a 3D scan, achieving competitive segmentation with less than 1% labeled data.
Alibaba DAMO Academy
Researcher · Alibaba Star Program
Alibaba Taotian
Research Intern · T-Star Program, LLM4Rec (large language models for recommendation)
Shanghai AI Lab
Research Intern · Multimodal models and human-centric foundation models
SenseTime
Research Intern · Vision-language models
National-level academic honor · 2025
University-level distinction · 2026